

By Chander Chadha, Director of Product Marketing, Storage Products, Marvell
As AI models grow larger and inference workloads scale, larger models, longer context windows and growing KV caches are driving demands on memory resources. Traditional CPU-centric networked JBOF (Just Bunch of Flash) can’t keep pace with the throughput, latency, and efficiency requirements of these modern AI clusters.
DPU (data processing unit) -based storage is a compelling alternative to traditional storage, acting as the broker between the network and SSD for remote storage. By offloading storage, networking and security processing from the host CPU onto a dedicated DPU, AI infrastructure can move data closer to compute, reduce latency, and free up valuable CPU cycles for AI workloads.
To address this need, Marvell offers the OCTEON DPU family, purpose-built for hyperscale cloud workloads and data center applications, extending its use specifically into network storage acceleration for AI environments.
By Khurram Malik, Associate Vice President, Custom Cloud Solutions, Marvell
The rapid growth of AI is creating unprecedented demand for memory capacity. As models get larger and workloads become more data-intensive, traditional server architectures are increasingly challenged to scale memory efficiently.
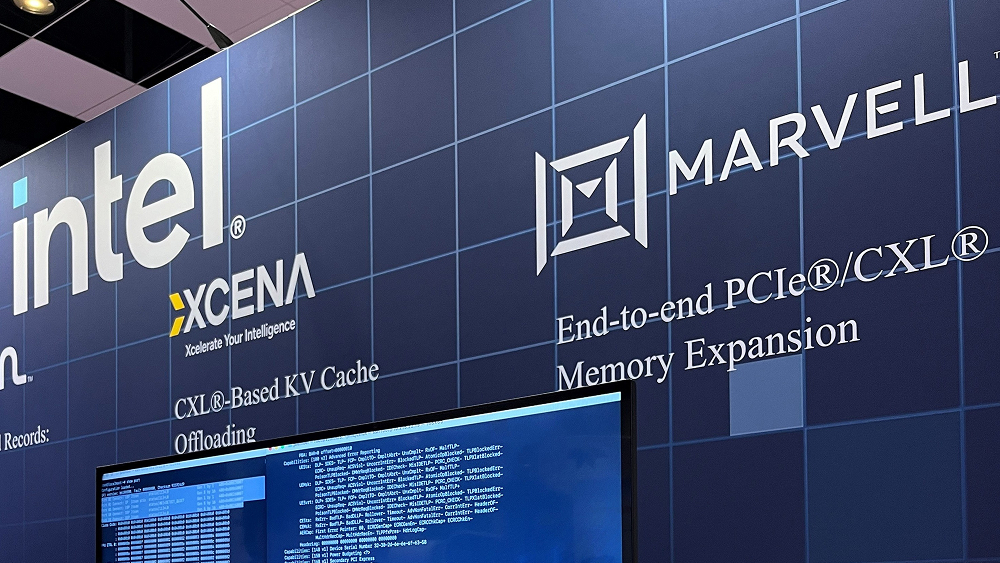
At Flash Memory Summit (FMS), Marvell demonstrated how CXL can enable a more flexible and scalable approach to memory infrastructure, showcasing an end-to-end architecture at the Intel® booth.
The demonstration combined an Intel platform with three Marvell® technologies: Structera® X CXL memory expander, Structera® S CXL switch and Alaska® P PCIe retimer. Together, they demonstrated how memory expansion, CXL switching and high-speed PCIe connectivity can work together within a real server platform.
By Arifur Rahman, Director of Product Marketing, Custom Cloud Solutions, Marvell
Memory has become the defining constraint of modern AI infrastructure. Large language models, in-memory databases, and deep learning recommendation models all share the same bottleneck: there is never enough DRAM. Compute Express Link (CXL) was designed to break that bottleneck but a CXL memory expander is only as valuable as the breadth of platforms it can run on.
That is why ecosystem enablement is a core pillar of Marvell's CXL strategy. Today we are marking a new milestone: successful interoperability of the Marvell® Structera™ X CXL memory-expansion controller with the NVIDIA Vera CPU platform.
By Uniquely Wired, Profile of Angelina Totović, Principal Engineer, Photonic Fabric Business Unit, Marvell
This article was originally published in Uniquely Wired.
The frontier of photonics is among the least predictable corners of modern engineering, a place where quiet research can grow into $5.5 billion dollar acquisitions inside a five-year window, and where the engineers closest to the science are often so invested in the technological developments that they are the last to learn how much value they have actually created. Angelina has been inside that turbulence from the start. The deal Marvell struck with Celestial AI in late 2025, the largest event in her professional life so far, arrived through her newsfeed the same way it arrived for everyone else. The role she holds today did not exist when she first sat down to work on the technology that produced it. Read across the whole arc, her career has been one long exercise in learning to work with things she could not predict.
By Khurram Malik, Associate Vice President, Custom Cloud Solutions, Marvell, and Kangkyu Park, Vice President, System Architecture, SK hynix
The rapid growth of AI workloads is creating unprecedented demands on data center architectures. Modern AI applications, including large language models (LLMs), generative AI, recommendation systems, and high-performance computing, require significantly higher memory capacity, bandwidth, and efficiency.
Traditional compute-centric architectures are increasingly limited by the movement of data between processors and memory. As AI models continue to scale, excessive data movement creates performance bottlenecks, increases latency, and drives higher power consumption.
To address these challenges, the industry is moving toward memory-centric computing architectures enabled by Compute Express Link® (CXL®). CXL enables flexible memory expansion, memory pooling, and new system architectures that allow compute resources to operate more efficiently.
Marvell and SK hynix are collaborating to enable the next generation of memory-centric computing by combining Marvell® Structera™ A CXL-based near-memory acceleration technology with SK hynix advanced memory solutions. Together, Marvell and SK hynix are helping accelerate the adoption of CXL-enabled architectures for AI data centers by delivering a highly efficient and scalable approach to memory processing.