

By Arifur Rahman, Director of Product Marketing, Custom Cloud Solutions, Marvell
AI and ML workloads are rewriting the rules of data center design. Memory demands are reaching an unprecedented level due to growing LLM sizes, expanding context windows and growing KV-cache requirements. Traditional servers are not architected to meet this surge. Memory has become the primary bottleneck constraining AI performance and infrastructure efficiency. CXL-based memory expansion has emerged as one of the definitive architectural answers, and Marvell is raising the bar.
Building on the strong market adoption of the first-generation Structera® X CXL controllers, the second-generation Structera X 3406 and Structera X 3506, co-developed and co-architected with leading hyperscalers, address the most demanding AI infrastructure requirements.
Modern AI inference workloads, from LLM serving to deep learning recommendation models (DLRM), are memory bound. KV-cache capacity determines time-to-first-token (TTFT), throughput and XPU utilization. When memory runs out, performance collapses.
By Rajagopal Krishnaswamy, Associate Vice President, Product Marketing, Marvell
The networking industry has fully embraced the benefits of open networking. Organizations building cloud infrastructure, AI clusters, enterprise data centers and edge networks want the flexibility to choose the hardware and software solutions that best meet their requirements. Software for Open Networking in the Cloud (SONiC) has emerged as a powerful foundation for achieving that flexibility, enabling customers to adopt an open, community-driven network operating system across diverse environments.
But deploying SONiC in production requires more than installing software on a switch.
As networks grow in scale and complexity, organizations need validated software, operational visibility, lifecycle management, automation, and enterprise-grade support. Running modern infrastructure successfully requires a complete operational framework that helps teams deploy, manage, troubleshoot and evolve their networks over time.
That reality is driving the next phase of SONiC adoption.
By Abed Mohammad Kamaluddin, Director, Custom Cloud Solutions, Marvell, and Vienna Alexander, Marketing Content Professional, Marvell
For most of the last decade, scaling AI meant scaling compute. If you built faster accelerators and wired enough of them together, the models would follow.
That is no longer the whole picture. Models now run to hundreds of billions of parameters with extensive context windows, and whether an expensive accelerator is working or just waiting comes down to memory: how much you have, how fast you can reach it, and how much time you lose moving data around.
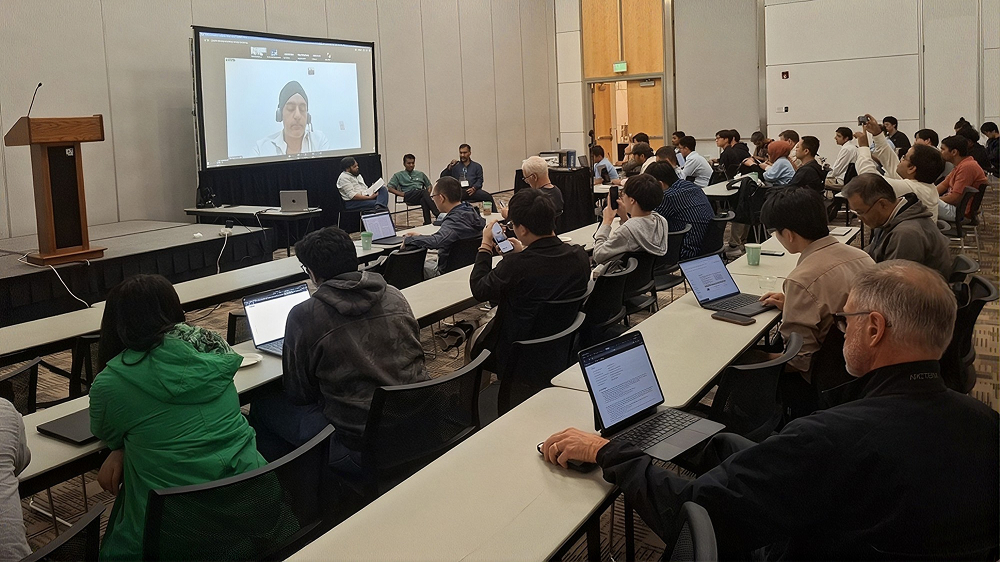
Once memory leaves the server and rides a switched fabric, is it still memory, or has it become a network? This was the central question of MemNetAI, the first workshop on Memory-Semantic Networking for AI-Scale Systems, launched by Marvell with researchers from IIT Hyderabad and IIIT Delhi. Held at ACM SIGCOMM 2026 in Denver and guided by a program committee spanning academia and industry, it brought speakers from Cornell, alongside industry experts and researchers presenting their work, to debate these questions on the bleeding edge of AI infrastructure.
By Chander Chadha, Director of Product Marketing, Storage Products, Marvell
As AI models grow larger and inference workloads scale, larger models, longer context windows and growing KV caches are driving demands on memory resources. Traditional CPU-centric networked JBOF (Just Bunch of Flash) can’t keep pace with the throughput, latency, and efficiency requirements of these modern AI clusters.
DPU (data processing unit) -based storage is a compelling alternative to traditional storage, acting as the broker between the network and SSD for remote storage. By offloading storage, networking and security processing from the host CPU onto a dedicated DPU, AI infrastructure can move data closer to compute, reduce latency, and free up valuable CPU cycles for AI workloads.
To address this need, Marvell offers the OCTEON DPU family, purpose-built for hyperscale cloud workloads and data center applications, extending its use specifically into network storage acceleration for AI environments.
By Khurram Malik, Associate Vice President, Custom Cloud Solutions, Marvell, and Kangkyu Park, Vice President, System Architecture, SK hynix
The rapid growth of AI workloads is creating unprecedented demands on data center architectures. Modern AI applications, including large language models (LLMs), generative AI, recommendation systems, and high-performance computing, require significantly higher memory capacity, bandwidth, and efficiency.
Traditional compute-centric architectures are increasingly limited by the movement of data between processors and memory. As AI models continue to scale, excessive data movement creates performance bottlenecks, increases latency, and drives higher power consumption.
To address these challenges, the industry is moving toward memory-centric computing architectures enabled by Compute Express Link® (CXL®). CXL enables flexible memory expansion, memory pooling, and new system architectures that allow compute resources to operate more efficiently.
Marvell and SK hynix are collaborating to enable the next generation of memory-centric computing by combining Marvell® Structera™ A CXL-based near-memory acceleration technology with SK hynix advanced memory solutions. Together, Marvell and SK hynix are helping accelerate the adoption of CXL-enabled architectures for AI data centers by delivering a highly efficient and scalable approach to memory processing.